
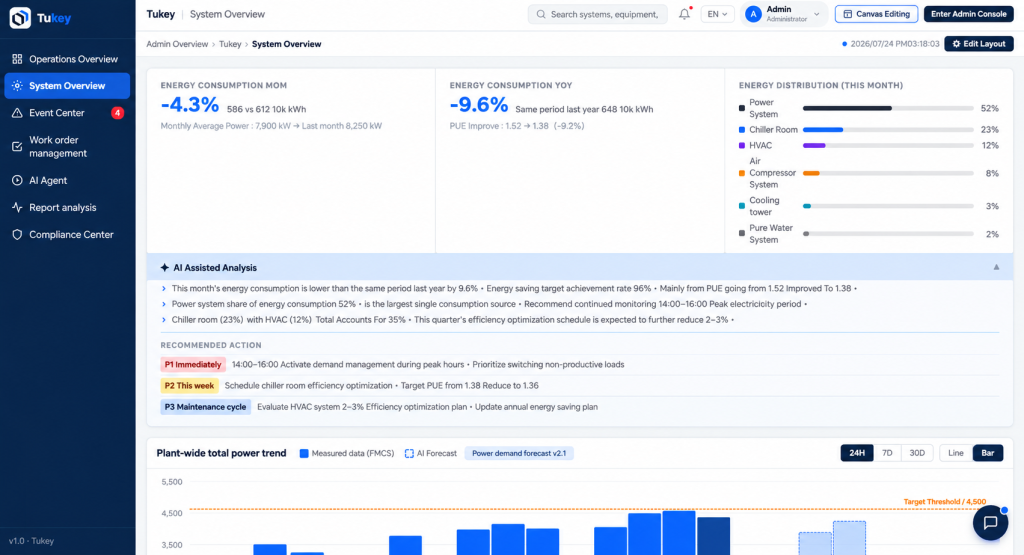
Chimes AI, the industrial AI software company, is advancing its Tukey AI Platform by combining Machine Learning with Generative AI to help manufacturers move beyond equipment anomaly detection toward root cause analysis and actionable maintenance recommendations.
Tukey originally concentrated on AutoML applications including Predictive Health Management, Parameter Optimization, and Virtual Quality Prediction. As Chimes AI expanded its Generative AI capabilities, demanding LLM inference, long-context processing, and RAG workloads placed increasing pressure on its existing computing environment.
To overcome these performance limitations, Chimes AI leverages an inference-ready FPT AI Factory platform powered by NVIDIA HGX H100 GPUs to run Qwen3.6-27B with vLLM. The high-performance GPU Cloud enables faster AI-assisted analysis and provides a stronger foundation for next-generation Industrial GenAI services.
In a 2K-input benchmark, Chimes AI reduced end-to-end latency from 9.54 seconds to 3.28 seconds, achieving approximately 2.9X faster inference compared with its previous PRO5000 GPU environment.
With the computing foundation provided by FPT AI Factory, Chimes AI is continuing to evolve Tukey from predictive AI toward Industrial GenAI that helps manufacturers reduce unplanned downtime, improve operational safety and efficiency, and ultimately support more sustainable manufacturing operations.
Challenges
| Moving Beyond Predictive AI
Machine Learning can identify equipment anomalies and potential failures, but engineers still need to investigate root causes, retrieve SOPs and maintenance records, and determine the next action. |
| Increasing GenAI Compute Demand
Large language models, long-context processing, and RAG require higher GPU performance to deliver responsive Industrial AI applications. |
| Inference Performance Limitations
The previous PRO5000 GPU environment limited the performance of larger models, particularly for long-context and RAG workloads. |
Solutions
| High-Performance Computing with FPT AI Factory
Leverage NVIDIA H100 GPUs on FPT AI Factory to run Qwen3.6-27B with vLLM for LLM inference, RAG, and AI-assisted analysis. |
| Machine Learning + Generative AI
Combine Machine Learning predictions with Generative AI to interpret equipment risks, analyze root causes, retrieve relevant knowledge, and generate prioritized maintenance recommendations. |
Benefit
| 2.9X Faster Inference
Reduce end-to-end latency from 9.54 seconds to 3.28 seconds in a 2K-input benchmark compared with the previous PRO5000 environment. |
| Faster Path from Detection to Action
Enable engineering teams to move more efficiently from anomaly detection to root cause analysis and maintenance recommendations. |
| Improved Industrial Operations
According to Chimes AI, its Industrial AI solution achieves over 90% anomaly detection accuracy, with up to 30% reduction in unplanned downtime and up to 50% reduction in maintenance labor time. |